A traditional web application does what its code says. An LLM application does what its code says, plus whatever the model infers from every piece of text it reads. That text can include a customer email, a scraped web page, or a PDF someone uploaded, and the model cannot reliably tell which parts are data and which are instructions.
This is why AI security needs adversarial testing that goes beyond scanning for known vulnerabilities. You have to probe a probabilistic system whose behavior shifts with phrasing, conversation history, and context. Red, blue, and purple teaming give you a structure for doing that.
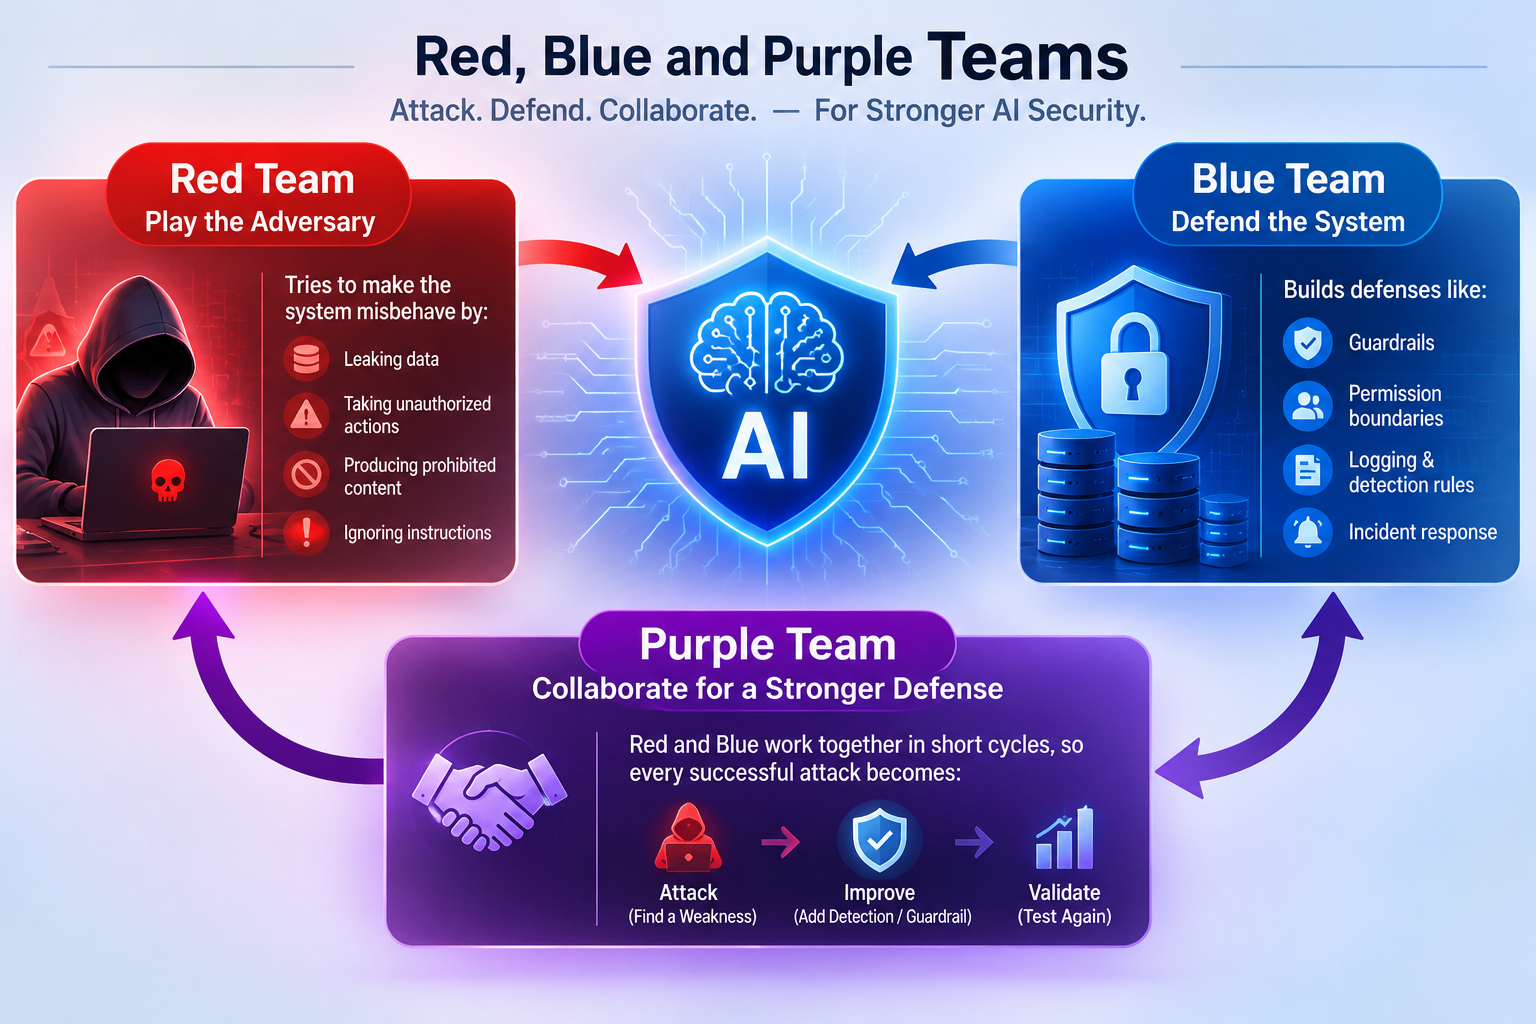 Source: Generated using AI
This guide covers how the three disciplines map onto AI systems, how jailbreaking and prompt injection work conceptually, what a continuous testing pipeline looks like, and where the limits are. It stays at the level of mechanisms and defenses and does not include working attack payloads.
Read on → Source: Generated using AI
 Source: Generated by AI
 Source: AI
 Source: AI